In the fascinating world of data science, regression plays a crucial role by allowing the modeling and forecasting of relationships between variables. This article invites you to explore the different facets of regression, with a particular focus on linear regression. With powerful tools like scikit-learn and statsmodels, discover how to apply these techniques to extract valuable insights from your data. Whether you are a beginner or an expert, dive into this universe and master the art of predicting the future from past information.
Regression
Linear regression is a fundamental statistical method used to model the relationship between a dependent variable and one or more independent variables. In Python, the scikit-learn library is often used to implement linear regression models. In this section, we will explore how to perform linear regression in Python, explaining essential concepts and providing practical examples.
Understanding linear regression
Linear regression aims to find the straight line that best fits a dataset. This line is defined by the equation:
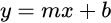
where (y) is the dependent variable, (x) is the independent variable, (m) is the slope of the line, and (b) is the y-intercept.
Implementation in Python
To implement linear regression in Python, we will use scikit-learn. First, let's import the necessary libraries:
First, we need to prepare our data. Suppose we have a simple dataset:
Next, we will create and train our linear regression model:
After training, we can use the model to make predictions:
Model evaluation
To evaluate the performance of our model, we can use metrics like the coefficient of determination (R^2), which indicates the proportion of variance explained by the model:
A (R^2) score close to 1 indicates that the model explains the variance in the data well.
Conclusion
Linear regression is a powerful and intuitive technique for exploring relationships between variables. With Python and scikit-learn, implementing this method is simplified, making data analysis accessible even to beginners.
Linear regression
In this section, we will delve deeper into linear regression, examining its practical applications and the different steps to optimize it. Linear regression is one of the most widely used methods in machine learning for predicting a continuous variable.
Applications of linear regression
Linear regression is used in various fields, such as:
- Economics: to predict consumption based on income.
- Biology: to model the growth of organisms over time.
- Marketing: to estimate sales based on advertising expenses.
Data preprocessing
Before building a linear regression model, it is crucial to preprocess the data. This includes:
- Data cleaning: Remove or impute missing values to avoid bias.
- Normalization: Scale the data so that all variables have equal importance.
Example of normalization in Python:
Model fitting
Once the data is prepared, model fitting involves finding the optimal values for (m) and (b) in the line equation. scikit-learn does this automatically when calling the fit() method.
Cross-validation
To ensure that the model is robust and generalizable, it is advisable to use cross-validation. This involves splitting the data into several subsets and training multiple models:
Residual analysis
Residual analysis—the difference between predicted and actual values—is essential for checking the assumptions of linear regression. A residual plot can help identify biases:
By following these steps, one can build an effective linear regression model and obtain reliable predictions while identifying possible improvements.
Python packages for linear regression
To effectively implement linear regression in Python, several libraries can be used. Each of them offers specific features that can simplify the modeling and data analysis process. Here is an overview of the most popular Python packages for linear regression.
scikit-learn
scikit-learn is undoubtedly the most used library for linear regression in Python. It is valued for its simplicity and flexibility. It includes tools for data preprocessing, model selection, and performance evaluation.
Example of linear regression with scikit-learn:
statsmodels
statsmodels is another powerful library for performing statistical analyses, including linear regression. It offers advanced features for residual analysis, coefficient interpretation, and checking statistical assumptions.
Example of linear regression with statsmodels:
numpy and scipy
Although numpy and scipy are not specifically dedicated to linear regression, they provide basic functions for performing linear and statistical calculations. They are often used alongside other libraries for custom calculations.
Calculating simple linear regression with numpy:
Each of these libraries has its advantages and is chosen based on the specific needs of the analysis. scikit-learn is ideal for general machine learning tasks, statsmodels for in-depth statistical analyses, and numpy/scipy for basic numerical calculations.
Simple linear regression with scikit-learn
In this section, we will explore how to perform simple linear regression using scikit-learn. This library, very popular for machine learning in Python, offers robust and easy-to-use tools for implementing this type of model.
Data preparation
Before starting, ensure that your data is ready. This includes splitting into training and testing sets, as well as normalization if necessary. Here is an example of data preparation:
Creating and training the model
Once the data is prepared, you can create a linear regression model and train it on the training set:
Prediction and evaluation
After training, the model can be used to make predictions on the testing set. You can then evaluate the model's performance using the R² score:
Interpreting the results
The R² score measures the proportion of variance in the data that is explained by the model. A score close to 1 indicates a good fit, while a score close to 0 suggests that the model does not explain the data well.
By using scikit-learn, you can easily fit and evaluate a linear regression model, making this library a preferred choice for machine learning projects.
Multiple linear regression with scikit-learn
Multiple linear regression is an extension of simple linear regression that allows modeling the relationship between a dependent variable and multiple independent variables. With scikit-learn, this task is just as simple to perform as simple linear regression. Let's see how to proceed.
Data preparation
To perform multiple linear regression, it is essential to have a dataset with multiple features. Here is how to prepare this data:
Creating and training the model
Creating and training the multiple linear regression model is similar to the simple version. The difference lies in using multiple features.
Prediction and evaluation
Once the model is trained, you can make predictions and evaluate its performance with the R² score, which indicates how well the model explains the variance in the data:
Interpreting the coefficients
In multiple linear regression, each coefficient in the model represents the impact of a given feature on the target variable, accounting for the other features. These coefficients can be extracted as follows:
Multiple linear regression with scikit-learn allows effectively modeling more complex relationships between multiple variables, making this approach valuable for advanced statistical analyses and accurate predictions.
Polynomial regression with scikit-learn
Polynomial regression is a technique that allows modeling the relationship between a dependent variable and one or more independent variables when that relationship is non-linear. By using scikit-learn, you can easily transform linear regression into polynomial regression by adding non-linear terms to the data.
Feature transformation
The first step is to transform the input features to include polynomial powers. scikit-learn offers the PolynomialFeatures module to generate these terms:
In this example, we transformed the input data into quadratic terms, allowing the model to learn a non-linear relationship.
Creating and training the model
After transformation, the model training process is similar to that used for simple and multiple linear regression:
Prediction and evaluation
After training the model, you can make predictions and evaluate performance using the R² score:
Visualizing results
To better understand the model's performance, it is often helpful to visualize the polynomial regression curve:
Polynomial regression with scikit-learn is a powerful tool for modeling complex relationships, enabling the capture of non-linear dynamics in your data.
Advanced linear regression with statsmodels
The statsmodels library is particularly useful for performing advanced statistical analyses in linear regression. It provides powerful tools for statistical modeling that go beyond model fitting, allowing for detailed interpretation of results.
Creating and fitting the model
With statsmodels, the process of creating an advanced linear regression model begins with manually adding a constant for the y-intercept:
Interpreting the results
Once the model is fitted, statsmodels provides a detailed statistical summary:
The summary includes essential information such as coefficients, standard errors, t-values, p-values, and confidence intervals, allowing for understanding the statistical significance of each independent variable.
Residual analysis
Residual analysis is crucial for checking the assumptions of linear regression, such as the normality of errors and homoscedasticity. Here’s how to visualize the residuals:
A residual plot showing a random distribution around zero indicates that the model is appropriate.
Hypothesis testing
statsmodels also offers advanced hypothesis tests, such as the White test for heteroscedasticity and the Jarque-Bera test for normality of residuals:
Using statsmodels for advanced linear regression allows for in-depth analysis and clear interpretation of results, essential for any rigorous statistical analysis.
Beyond linear regression
Linear regression is a powerful tool for modeling simple or multiple relationships between variables. However, it has limitations when it comes to capturing more complex or non-linear relationships. It is often necessary to explore other regression methods or machine learning techniques.
Logistic regression
Logistic regression is used when the target variable is categorical. It is particularly useful for binary classification problems, such as predicting the probability of an event occurring.
Ridge and lasso regression
To prevent overfitting in linear regression models, ridge and lasso regularizations can be applied. These methods add a penalty for the size of coefficients:
- Ridge: minimizes the sum of squared coefficients.
- Lasso: can reduce some coefficients to zero, allowing for feature selection.
Decision trees and random forests
To capture complex non-linear relationships, decision trees and random forests are powerful alternatives. Decision trees partition the feature space into smaller regions, while random forests use multiple trees to reduce the risk of overfitting.
Neural networks
For extremely complex and non-linear relationships, neural networks offer great flexibility. With libraries like TensorFlow or Keras, you can create neural network models tailored to your needs.
By exploring these alternative methods, you can choose the model that best fits your data and analysis goals.
Conclusion
Linear regression is a fundamental technique that provides a solid starting point for analyzing relationships between variables. It is widely used due to its simplicity and ability to provide interpretable results. Throughout this article, we have explored various applications of linear regression, from its simple form to its multiple and polynomial extensions, using powerful tools like scikit-learn and statsmodels.
Importance of linear regression
Linear regression plays a crucial role in many fields, from economics to biology, marketing, and social research. It not only allows predicting continuous values but also helps to understand the underlying relationships between variables, thus facilitating data-driven decision-making.
Exploring alternatives
Although linear regression is a powerful tool, it has its limits, especially when it comes to modeling non-linear relationships or when the data exhibits high multicollinearity. That's why it is essential to explore alternative methods such as logistic regression, ridge and lasso regularizations, as well as more advanced techniques like decision trees, random forests, and neural networks.
These alternatives can offer better accuracy and the ability to capture complex dynamics within the data. The choice of method will depend on the specifics of each project, the nature of the data, and the goals of the analysis.
Future perspectives
With the advent of big data and the rise of machine learning, the future of regression, whether linear or otherwise, is promising. New technologies and algorithms continue to expand the possibilities of what can be accomplished with data, offering exciting prospects for predictive analysis and modeling.
In conclusion, mastering linear regression and its variants provides a solid foundation for any advanced statistical analysis. Whether you are a beginner or an expert, understanding the fundamental principles and being able to apply these techniques will allow you to make the most of your data, contributing to more informed decisions and innovative solutions.