Taught by Tech Leads

Master pipelines, cloud & AI to become an operational Data Engineer.

DataScientist.fr
Image de LangChain Text Splitters: Advanced Guide
Artificial Intelligence
LLM
Python

LangChain Text Splitters: Advanced Guide
Photo de Romain DE LA SOUCHÈRE

Tech Lead, CTO AXI Technologies

Published on 14 mai 2025 · 10 min of reading

Text splitting is a crucial preprocessing step when using language models, particularly in the field of NLP (Natural Language Processing). LangChain provides several effective methods to perform this operation. This article aims to delve into these techniques, clarifying their theoretical and practical significance, while presenting concrete cases and recommendations suitable for students specializing in this field.

Why is splitting essential?

Text splitting is fundamental for several technical and practical reasons:
  • Standardization of inputs: The corpora used in NLP often contain documents of very varying sizes. Splitting ensures a homogeneous and simplified management of these documents.

  • Respecting model limits: Language models, particularly Transformers, have a maximum token limit that they can process simultaneously. Splitting the text allows one to circumvent this constraint.

  • Quality of embeddings: By limiting the size of the segments, one improves the accuracy of embeddings by reducing the semantic ambiguities caused by overly large blocks of text.

  • Optimization of RAG (Retrieval-Augmented Generation) systems: Providing precise contexts significantly improves the relevance of retrieved information and the quality of responses generated by the models.

  • Computational efficiency: Splitting reduces memory and computational resource needs, allowing for better process parallelization.

  • Improvement of information retrieval: Search and summarization queries become more precise thanks to better defined and structured text units.
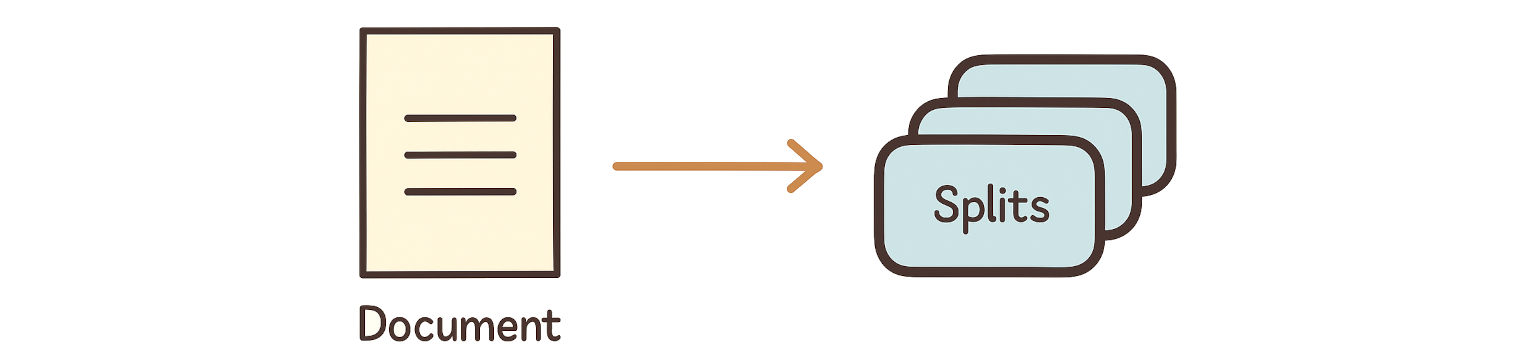
text splitter
Let’s look at some splitting techniques:

Size-based splitting

This simple and straightforward method splits the text according to a predefined maximum size (in terms of tokens or characters). It is generally a purely quantitative criterion.
Advantages:
  • Easy implementation

  • Regularity and precise control of segment sizes

  • Ease of adaptation to the specific requirements of the models used

Potential disadvantages:
  • Risk of breaking sentences or losing context if the cut is poorly placed

Example - CharacterTextSplitter:

python

Recursive splitting based on linguistic structure

This approach exploits the natural hierarchy of the text: it first attempts to split the text by paragraphs, then by sentences, and finally by words if necessary. This hierarchy generally ensures better semantic coherence of the resulting segments.
Advantages:
  • High semantic coherence

  • Automatic adaptation to the linguistic structure of the text

Potential disadvantages:
  • Can generate segments of very varying sizes depending on the type of text

Example - RecursiveCharacterTextSplitter:

python

Splitting based on document structure

This method is ideal for documents with a clear formal structure, such as Markdown, HTML, or JSON files. The splitting explicitly exploits tags, titles, or hierarchical structures defined in these formats to maintain contextual coherence.
Advantages:
  • Preserves context and the explicit semantic relationships defined by the original structure

  • Very useful for structured information extraction or automatic summarization

Potential disadvantages:
  • Limited to documents with a defined explicit structure

Example - MarkdownHeaderTextSplitter:

python

Semantic splitting

Semantic splitting uses embeddings (semantic vectors) to identify significant changes in meaning within the text. The resulting segments are then very homogeneous semantically.
Advantages:
  • Extremely coherent segments at the semantic level

  • Particularly suitable for enhancing information retrieval systems

Potential disadvantages:
  • Increased computational complexity due to the calculation of embeddings

  • Dependent on the quality of the embedding model used

Example - SemanticChunker:

python

Conclusion

The splitting methods proposed by LangChain are key tools for students and researchers in NLP looking to fully leverage their models. By mastering these techniques, you will effectively optimize your data preparation and achieve notable improvements in the overall performance of your natural language processing systems.

Want to go further?

This topic is part of our Generative AI for Developers course. Browse the full programme, or get it by email.

Share with
Photo de Romain DE LA SOUCHÈRE

Romain DE LA SOUCHÈRE

Tech Lead, CTO AXI Technologies

Expert Data Engineering et Cloud, Romain affiche plus de 11 ans d'expérience, dont plusieurs années comme Lead Developer sur des solutions Smart Building haute performance. Il y a conçu et mis en production des moteurs de traitement capables d'absorber des centaines de milliers de données de capteurs par minute, ainsi que des bases clusterisées gérant plus de 10 millions de données dynamiques. Certifié Microsoft Azure DevOps Engineer Expert, il maîtrise aussi bien le développement back-end (Python, C#) que le DevOps (Docker, Kubernetes, Terraform) et les agents LLM. Formateur en Python, cloud, DevOps et IA générative appliquée, il forme avec une obsession : Amener chaque apprenant à concevoir et déployer des architectures réellement scalables en production.

» Learn More

Associated trainings

All our trainings
Image de la formation Generative AI for Developers
Generative AI for Developers
50 hours
Intermediate
Guarantee

Associated articles

See all our articles
Image de l'article Create a ReAct Agent with LangGraph

avril 18, 2025

Create a ReAct Agent with LangGraph

Reading time: 10 min

Image de l'article Practical Guide to Using Tools with LangChain

avril 15, 2025

Practical Guide to Using Tools with LangChain

Reading time: 5 min